Extend Global Torque with Event-Driven Cloud Run Workers
When a financial platform adds a CRM update, an accounting entry, or a customer notification, the tempting approach is to teach every service about every downstream provider. That works for the first connection. It becomes expensive as each provider adds credentials, error handling, release coupling, and a path through the core transaction.
A focused worker keeps the boundary small. A service accepts a business change, publishes an event, and a separate Cloud Run worker handles one integration concern. The payment service does not need to know how Salesforce works. The ownership service does not need to know which email provider an operations team prefers. Each worker can be released, scaled, and replaced around its own adapter while the financial workflow keeps its core responsibilities.
Start with a business event
Global Torque uses Distribute Finance to describe coordination across independent banks, custodians, identity providers, blockchains, administrators, and other providers. It is a financial coordination model, not shorthand for DeFi. The Distribute Finance overview explains why payment, asset delivery, and authoritative ownership records are separate facts that may finish at different times. The companion guide, Integrating with Torque: Less to Build, Less to Maintain, shows how a supported workflow can stay focused while each provider keeps its own role.
That model gives integrations useful business boundaries. Examples include:
- eligibility accepted under a particular policy version;
- payment confirmed against a provider reference; and
- ownership updated in the authoritative asset record.
An event says that an accepted change happened. It does not grant every consumer permission to perform a financial action. A worker validates the message, reloads the current state from the authoritative API or database it is allowed to use, and then decides whether its own side effect is still permitted. This keeps a CRM or reporting update from becoming an accidental source of settlement truth.
Why event-driven workers fit the platform
In an event-driven architecture, a producer records a change and consumers react independently. The Google Cloud event-driven architecture guide describes the pattern using asynchronous messages between components. In practice, that lets a request complete without waiting for every downstream provider to respond.
The useful distinction is between a business event and a raw database notification. PostgreSQL and the owning service API remain authoritative. A local transaction can save the accepted state change and an outbox record together; a relay can then publish the business message. Change-data-capture infrastructure may carry that record to Pub/Sub, but not every changed row is a business fact. A separate raw CDC notification stream can serve infrastructure concerns without becoming the business event contract, and replaying a projection must never resend a payment, mint, or transfer.
Cloud Run makes the worker boundary familiar to teams that already ship HTTP containers. The Pub/Sub Cloud Run tutorial covers receiving messages in a Cloud Run service, and Pub/Sub push delivery explains the authenticated HTTP delivery model. The platform can give each audited worker its own push subscription and scoped service identity. That makes ownership and operations visible: one worker can process CRM updates, another can write accounting records, and a third can send notifications from the same event.
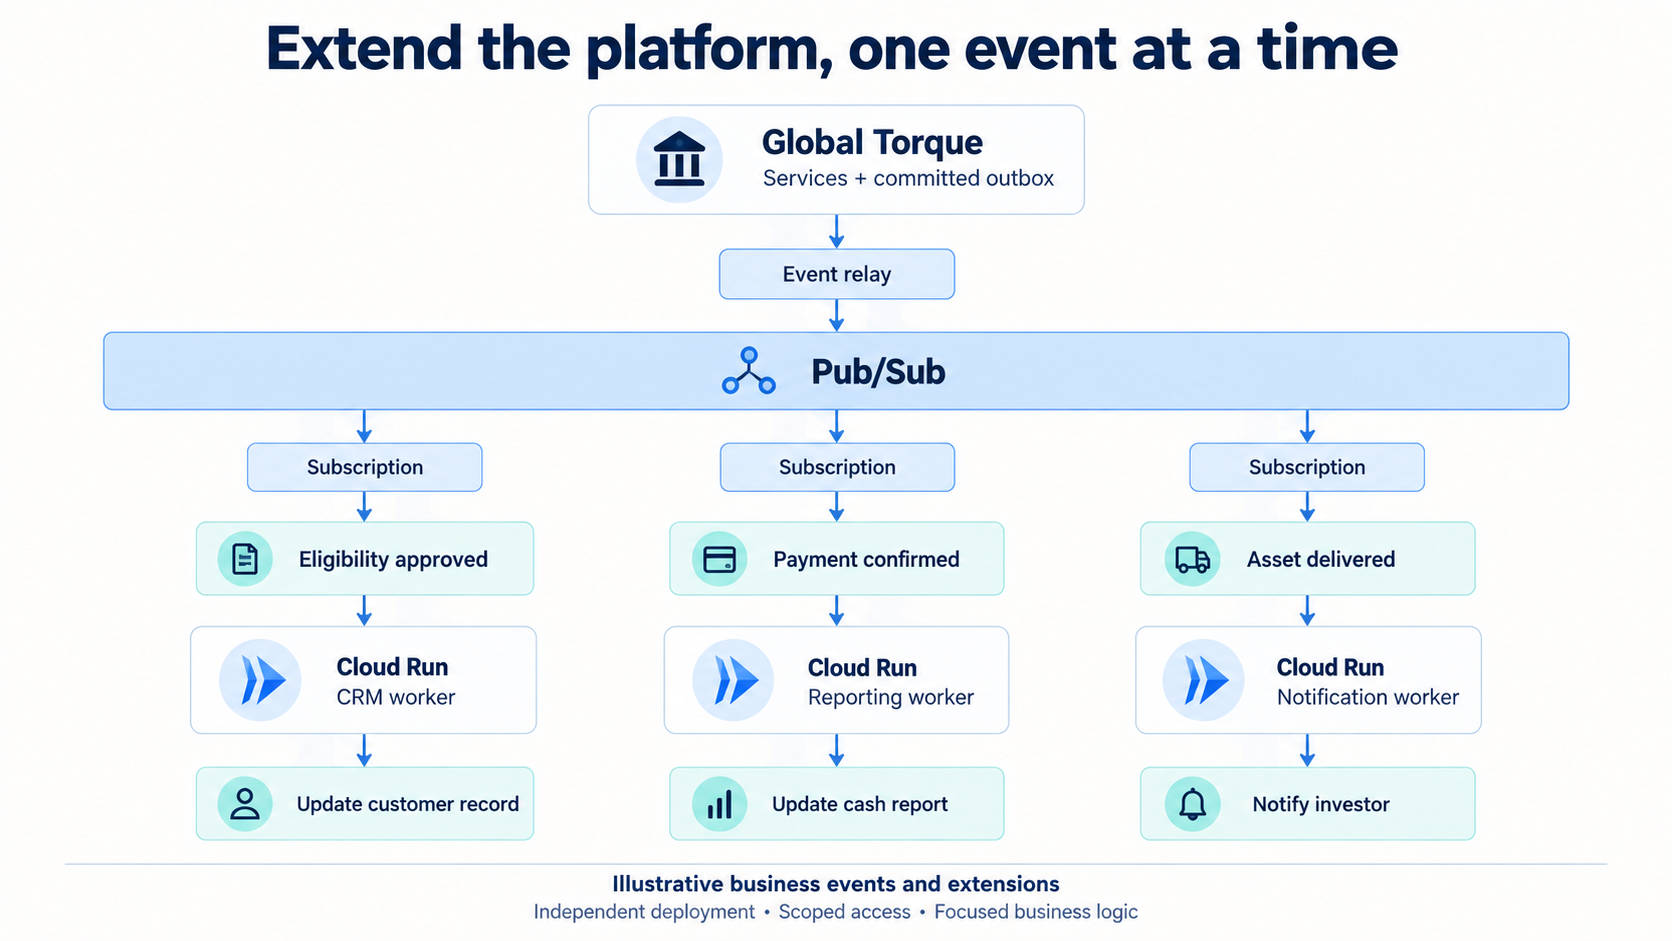
Illustrative architecture: the event labels show business concepts, not literal public API names. The linked PNG opens the full-resolution diagram. On a small screen, the table below provides the same relationships in readable text.
| Illustrative business event | Focused worker action | Engineering benefit |
|---|---|---|
| Eligibility accepted | Update the CRM profile and workflow status | CRM changes stay outside the eligibility service and can evolve independently. |
| Payment confirmed | Record the provider reference in accounting or reporting | Financial reporting has a dedicated adapter without extending the payment request path. |
| Asset delivered | Send an investor or operations notification | Notification delivery can retry and scale without holding the delivery write open; authoritative ownership can complete on its own path. |
One event can fan out to multiple independent subscriptions, so CRM, accounting, and notification work can proceed in parallel. Replicas sharing one subscription distribute deliveries between themselves; they do not each receive a private copy. This distinction helps teams choose the right subscription layout and avoid duplicating a side effect accidentally.
Build a worker around one integration
An extension usually follows a short sequence:
- Agree on the supported event, schema version, access scope, and authoritative source. Define which business change the worker consumes and which result it owns.
- Implement a small HTTP receiver and an adapter for the target system. Validate the envelope, event identity, schema, and authorization before calling the provider.
- Deduplicate by a stable event or effect identity. Re-read current state before an irreversible or consequential action, because a message can be delayed or arrive after a newer state.
- Package the worker as a container with a scoped service identity and app-owned settings and secrets. Keep provider credentials and endpoint configuration in the deployment environment.
- Have the platform or infrastructure owner attach a separate authenticated push subscription. Configure retry and dead-letter behavior for the worker’s failure mode and retention needs.
- Rehearse duplicates, out-of-order delivery, delayed provider responses, worker restarts, and an unavailable downstream system before enabling the integration.
The platform or infrastructure owner provisions the subscription and delivery identity. A team can then add one connection by owning one small receiver and its provider behavior, while the core platform continues to own the financial workflow and its authoritative records.
Keep delivery reliable and outcomes honest
Pub/Sub delivery is at least once. A worker must tolerate duplicates and should not assume events arrive in business order. A stable effect identity, a durable deduplication record, and a current-state read make handling repeatable, but final safety also depends on the provider’s retry and idempotency guarantees. Verify those guarantees before enabling the worker. If an external payment or transfer may already have happened but the response is missing, reconcile the provider before trying again. A successful Pub/Sub acknowledgement confirms transport handling; it does not confirm financial settlement, legal finality, or ownership registration.
Retry and dead-letter controls are configured per subscription and worker. They are useful tools for bounded recovery, but they do not make every action safe to repeat. An unknown external outcome needs a provider-specific reconciliation path and an accountable owner.
Cloud Run also keeps operational ownership clear. Cloud Run autoscaling lets each worker respond to its own request, CPU, and concurrency profile, with configurable bounds and zero idle instances by default. Teams can deploy a worker with health checks, a bounded identity, and configuration appropriate to its integration. A provider replacement then happens at the worker boundary rather than across every producer and frontend.
What is implemented and what is agreed per deployment
The documented DEV path writes outbox_events in the business transaction, Debezium reads PostgreSQL pgoutput, and Pub/Sub delivers to POST /pubsub/domain-events. The internal EVM worker then validates and routes the authenticated push, reloads authoritative state, and guards whether its permitted action can proceed. Status events such as investment.status.changed.v1 and evm-wallet-operation.status.changed.v1 trigger that inspection; they do not unconditionally mint or make a payment. Infrastructure manages the image, service identity, resource limits, health checks, and settings. This verified pattern is concrete; customer CRM, accounting, reporting, and notification extensions remain illustrative until their event contract, access, provider credentials, and subscription provisioning are agreed for a deployment. Broader orchestration through proposed Torque Flow is a separate product direction.
For a technical team, the next step is practical: choose one business event, one downstream responsibility, and one recovery rehearsal. Book a call with Global Torque to map that boundary and estimate the smallest maintainable worker for your platform.